
My Résumé Is a JSON Blob. AI Does the Rest.
Building a job-search harness taught me that the hard part of automation isn't generating documents. It's knowing what you're willing to put your name on.
My résumé is a JSON blob. AI does the rest.
There are still PDFs involved. I'm looking for a job, and employers have some very specific ideas about which rectangles they want uploaded into which other rectangles.
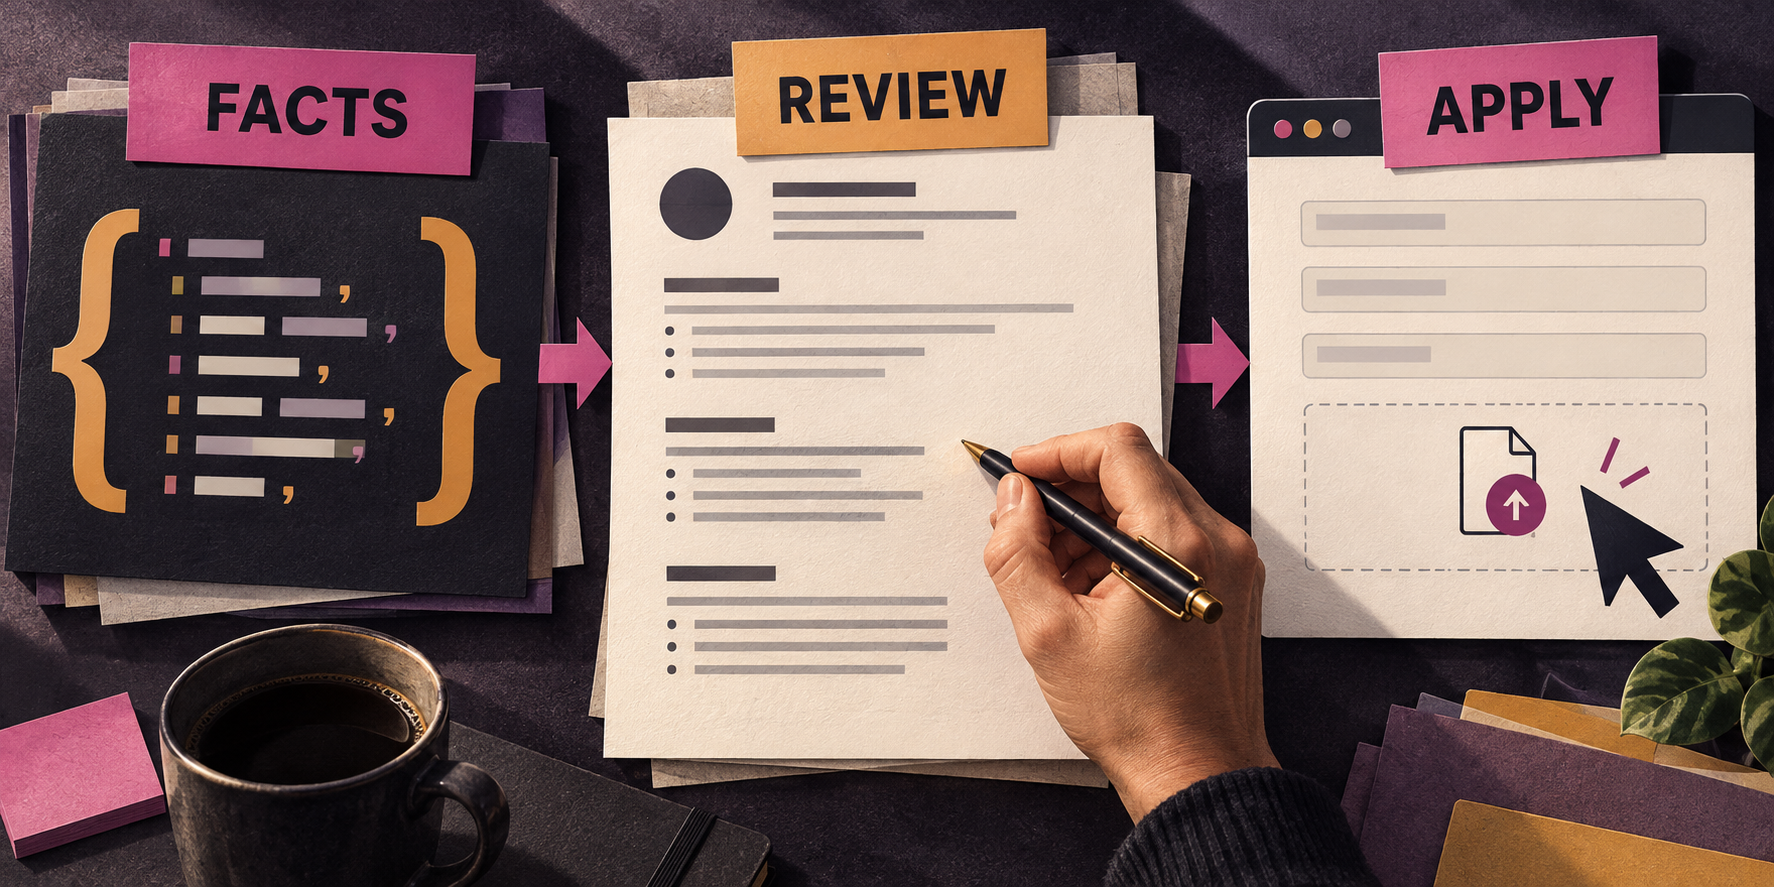
But the PDF is an output now. Underneath it is an account of what I've done, with sources, review states, and a history of corrections. The harness matches those facts to a role and helps prepare the application. I read the result and approve what goes out.
This changes where the work lives. Instead of opening another copy of my résumé and shuffling the same bullets around, I can start with the facts and ask which ones make an honest case for this job.
I'm looking for hands-on AI work, so I built a job-search harness for myself. I built it MCP-first. Facts, leads, drafting, and review all happen inside the AI harness.
Naturally, the interesting part turned out to be everything that happens between "make me a résumé" and clicking Submit.
Start with what actually happened
The foundation is a private bank of career facts on my Mac. What I did. What I owned. Which results I can support. Each claim has a source note and a review state.
Imported claims start unreviewed. I have to stand behind them before they go into an application.
The built-in drafting system works from a saved job posting and reviewed claims. The model selects relevant claim IDs. The résumé variant is assembled from their approved text. It can help decide what deserves space; it doesn't get to quietly promote me into a more convenient candidate.
Tailoring still matters. A role focused on building needs different evidence from a role focused on adoption. The useful question is which parts of my experience make the case. If the case has a hole, I want to see the hole.
Keeping the truth current is still work.
The advantage is having somewhere to correct it and keep its history, rather than chasing a particularly flattering error through five documents.
The architecture is relatively straightforward:
Career facts become reviewed claims. Reviewed claims become tailored drafts. Drafts become PDFs. Approved PDFs become applications. Each transition should preserve enough evidence to explain what happened.
The interesting engineering lives in those transitions.
The PDF is the thing I need to read
There is a temptation, when you build a system like this, to make the machinery the deliverable. A bundle of files. A detailed packet. An impressive amount of preparation.
My actual requirement became much simpler: show me the résumé PDF.
I need to see what an employer will see. I need to check the emphasis, the wording, and whether the document makes sense as a whole. Then I need to approve the application that will leave my computer under my name.
We used Heinlein, the publishing pipeline I built for my books, to refine and standardize the PDF generation process.
Code reuse ftw.
The MCP export tool still produces a private review packet, including the claims and sources behind the draft. The employer-facing PDFs we used this week were prepared and reviewed separately within the harness. Those pieces aren't yet one seamless pipeline.
MCP is the working interface to the job-search cockpit. The assistant calls its tools to work with my career facts, review leads, and prepare drafts. I read the PDFs and approve applications in the same harness. When we reach an employer's form, I use computer use to do the actual applying.
"Human in the loop" gets much more interesting when you ask what the human actually approved.
The implemented batch-submission path binds an attempt to a particular draft version, content hash, and snapshot of its contents and claims. If the draft or its underlying claims change, the old approval can't quietly cover the new material.
It doesn't prove that the right attachment landed in an employer's form. That still needs checking in the browser. The software can preserve what I approved; someone still has to verify what actually went out.
Then the forms get involved
HR systems tend to be an accessibility nightmare. They're often the last systems to get refinement.
I review the materials and approve the application in the harness. Then the assistant uses computer use to work through the employer's forms in the browser. Computer use helps me get through that last step.
On October 8, I put the broader workflow through a day of actual applications. Ten were submitted with employer confirmations. Each resume was tailored for the role, based on my resume truths, and reviewed by me.
Those applications used separately reviewed materials and computer use in the browser, with confirmations recorded in local journals and, where saved, lead notes.
Ten applications took me ten minutes.
There was also an application I skipped.
Its required CRM question offered no truthful choice: either imply Salesforce experience I didn't have, or deny CRM integration experience I did have.
Completing the application would have required an answer I wasn't willing to stand behind.
We stopped there.
A system that optimizes for completed forms will eventually encounter a question it can only complete by misrepresenting you. It needs somewhere to put that situation besides "close enough." My harness errs on the side of caution here: a successful application workflow needs to know when not to apply.
Other friction was less philosophical. A required field could look filled and still fail validation. A local service could stop. An employer could accept an application while the local tracking update remained blocked.
Those are different problems, and collapsing them into one green checkmark would make the system less trustworthy.
The last one is particularly important. If an employer received the application and my tracker failed to update, submitting again is a terrible repair strategy.
That's why the local queue has an uncertain state. In that implemented path, an ambiguous outcome blocks another attempt until it is reconciled. The database records the evidence supplied to it; it cannot independently see inside the employer's system.
There are tests for stale approvals, competing workers, uncertain attempts, and conflicting receipts.
Testing for the wrong kind of success
The dangerous thing about automating a job search is that it's very easy to measure the wrong thing.
If my success metric is applications submitted, the system can improve that number by lying about my qualifications, applying to irrelevant jobs, or clicking Submit twice when a website behaves strangely.
All three would make a dashboard look productive. That doesn't mean it's effective.
I've been separating the things I can test deterministically from the things that require judgment. The first category is factual integrity. Tests deliberately introduce unreviewed claims and invented IDs to verify that neither can slip into the generated application copy.
This matters because asking a language model not to hallucinate is not the same as building a system that rejects unsupported claims. A prompt is an instruction. A constraint is something the software enforces.
The second category is operational reliability. We use synthetic employer records, mocked model responses, and real database operations to exercise failure cases.
- What happens when two workers try to claim the same application?
- What happens when I edit a résumé after approving it?
- What happens when a submission's outcome is uncertain?
- What happens when a receipt conflicts with one already recorded?
We also test whether those protections survive a restart or database restoration.
These are regression tests rather than subjective evaluations. Their job is to establish that the software maintains its guarantees when things go wrong.
The October 1 local validation covered unit, integration, and browser tests, including the local MCP interface, approval lifecycle, receipt handling, and recovery behavior. Those checks used synthetic data, not actual employer submissions.
That's an important distinction. Tests can establish that the state machine behaves correctly under controlled conditions. They cannot establish that an employer received the correct attachment.
The newsletter
Get the build notes.
I write about building AI systems in public—what worked, what broke, and what I’d do differently.
The third category is harder: evaluating the quality of the decisions. A résumé can contain nothing but true statements and still be a terrible résumé. It can emphasize the wrong experience, bury the strongest evidence, or fail to explain why I belong in a particular role.
That's where human review currently does much of the evaluation work.
I read the documents, assess their relevance to the posting, look for unsupported implications, and decide whether the application makes an honest case.
I want to turn more of these decisions into repeatable evaluations: representative job postings, known qualification gaps, approved career evidence, and examples of acceptable and unacceptable outputs.
Then I can compare changes to the drafting process against cases I've already judged, instead of assuming a newer prompt or model produces better results.
The automated coverage is strongest around factual boundaries and workflow safety. Relevance, persuasion, and ultimately hiring outcomes need more evidence.
Passing a test suite doesn't mean the agent made a good decision.
It means I've established some things it cannot get away with.
Something is better than nothing
I can demonstrate that the tested submission path rejects a changed draft under an old approval. I can't yet demonstrate that it consistently chooses the best résumé to approve.
I'm a big believer in something being better than nothing.
Not because quality doesn't matter. Quite the opposite.
Because you can't improve a system that doesn't exist.
I could have spent weeks designing the perfect evaluation framework before submitting a single application. Instead, I built enough to establish some useful guarantees, put the system to work, and started collecting evidence about what it couldn't do.
This is how I approach engineering generally.
Build the smallest useful thing. Observe what happens when it meets reality. Correct what you misunderstood. Repeat.
You can't iterate on a hypothetical.
That doesn't mean shipping whatever happens to compile. It means deciding which guarantees are necessary before a system becomes useful, and which questions can only be answered by putting it to work.
In this case, invented qualifications, silent changes to approved material, and ambiguous duplicate submissions were problems worth designing against early.
Whether the model consistently chooses the most persuasive evidence for a particular job is a different problem. It deserves evaluation. But I don't need to solve it completely before the system can help me prepare applications.
There's also a difference between process correctness, evidence correctness, and outcome correctness.
The process can follow every rule and still use an outdated fact.
The facts can all be accurate and still make a weak case.
The application can be excellent and still lead nowhere.
When something goes wrong, I want to understand why, preserve the example, and make it harder for the same failure to happen again.
The goal isn't to teach the agent how to pass the eval. It's to use the eval to discover where I haven't taught the system what success means.
What I'm actually trying to improve
Ten applications tell me we used the broader workflow to get applications out.
They don't tell me whether it improves hiring outcomes.
I don't have that result yet.
What I can inspect now is the quality of the decisions along the way.
Can I explain why the system recommended that I apply in the first place? Can I see a mismatch before applying? Can I distinguish an application that was accepted from one that was merely attempted?
I want to compare tailored applications against a baseline. I want to know how often my review catches a problem, how often the model selects the wrong evidence, and whether a change to the drafting process actually makes the result better.
Eventually, I want to understand whether all this machinery helps me find better opportunities, have better conversations, and get hired. Those are outcomes I have to measure, not benefits I get to assume because I built something clever.
For now, the system gives me a place to maintain the truth about my career, match that history to opportunities, and reduce the repetition of preparing applications. There are still gaps between the pieces. Some judgments remain entirely mine.
I still want a readable PDF at the end. Recruiters should be able to open a résumé without taking a guided tour of my software.
But behind that small document, I want a durable account of my work and a clear record of what I chose to say about it. The useful automation is everything that helps me make those choices without losing track of the truth.